Project import generated by Copybara.
GitOrigin-RevId: 1e13be30e2c6838d4a2ff768a39c414bc80534bb
This commit is contained in:
 MediaPipe Team
committed by
Sebastian Schmidt
Sebastian Schmidt
parent
63e679d99c
commit
4dc4b19ddb
+10
-10
@@ -24,7 +24,7 @@ MediaPipe Objectron is a mobile real-time 3D object detection solution for
|
||||
everyday objects. It detects objects in 2D images, and estimates their poses
|
||||
through a machine learning (ML) model, trained on the [Objectron dataset](https://github.com/google-research-datasets/Objectron).
|
||||
|
||||
 |  |  | 
|
||||
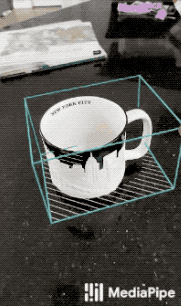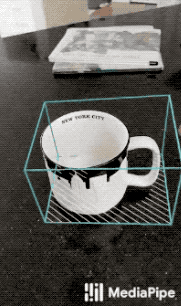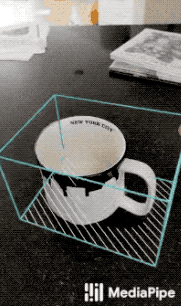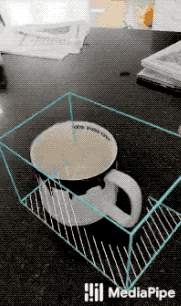
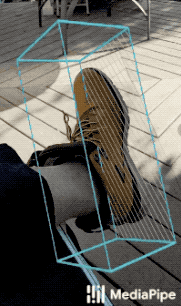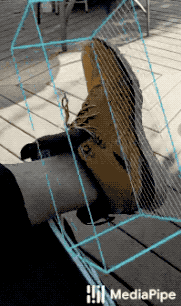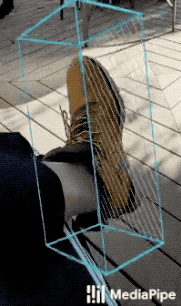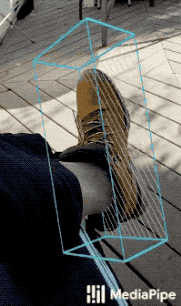 | 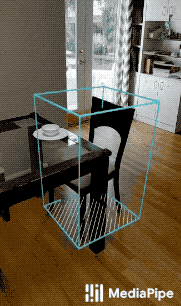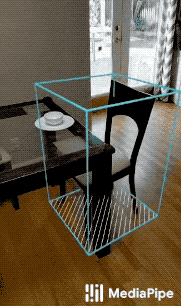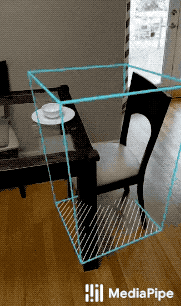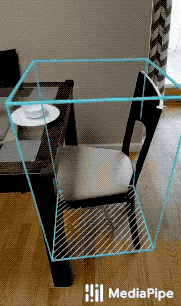 | 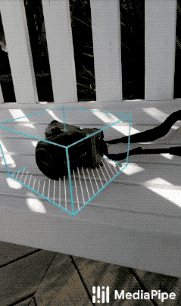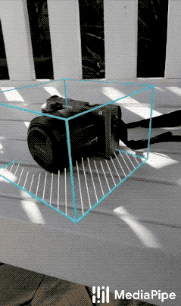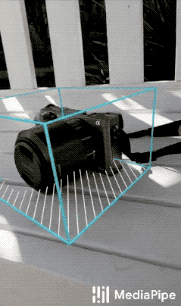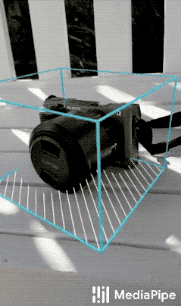 | 
|
||||
:--------------------------------------------------------------------------------: | :----------------------------------------------------------------------------------: | :------------------------------------------------------------------------------------: | :------------------------------------------------------------------------------:
|
||||
*Fig 1a. Shoe Objectron* | *Fig 1b. Chair Objectron* | *Fig 1c. Camera Objectron* | *Fig 1d. Cup Objectron*
|
||||
|
||||
@@ -39,7 +39,7 @@ mature and has been widely used in the industry, 3D object detection from 2D
|
||||
imagery is a challenging problem, due to the lack of data and diversity of
|
||||
appearances and shapes of objects within a category.
|
||||
|
||||
 |
|
||||
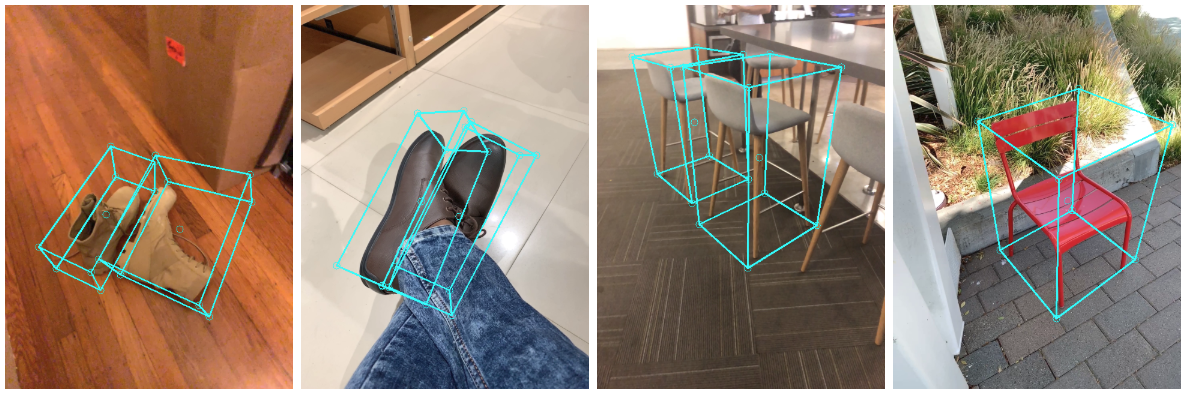 |
|
||||
:-----------------------------------------------------------------------: |
|
||||
*Fig 2. Objectron example results.* |
|
||||
|
||||
@@ -68,7 +68,7 @@ object in a single frame and propagate its location to all frames using the
|
||||
ground truth camera pose information from the AR session data, which makes the
|
||||
procedure highly efficient.
|
||||
|
||||
|  |
|
||||
| 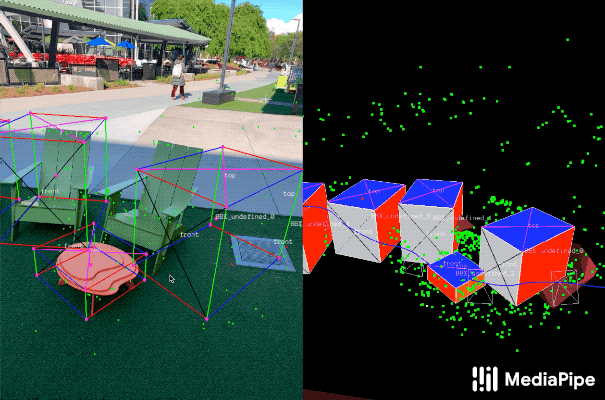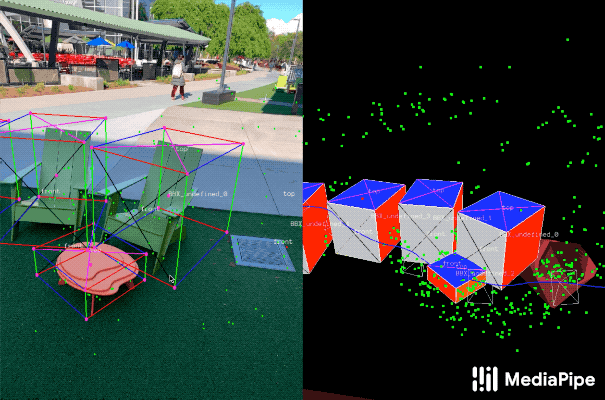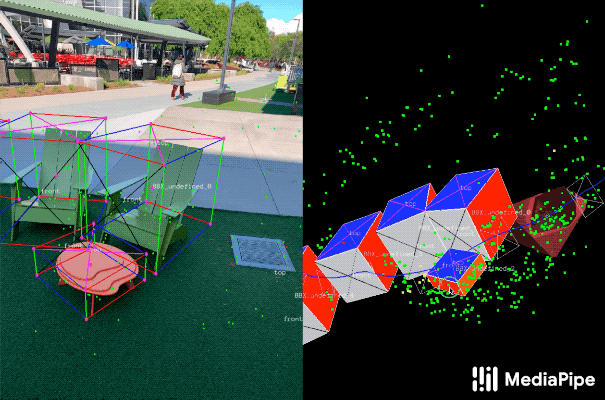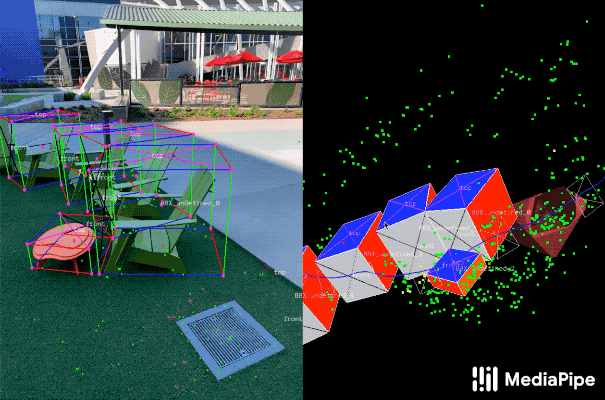 |
|
||||
| :--------------------------------------------------------------------------: |
|
||||
| *Fig 3. Real-world data annotation for 3D object detection. (Right) 3D bounding boxes are annotated in the 3D world with detected surfaces and point clouds. (Left) Projections of annotated 3D bounding boxes are overlaid on top of video frames making it easy to validate the annotation.* |
|
||||
|
||||
@@ -86,7 +86,7 @@ with rendered objects that respect the scene geometry and fit seamlessly into
|
||||
real backgrounds. By combining real-world data and AR synthetic data, we are
|
||||
able to increase the accuracy by about 10%.
|
||||
|
||||
 |
|
||||
 |
|
||||
:-------------------------------------------------------------------------------------------: |
|
||||
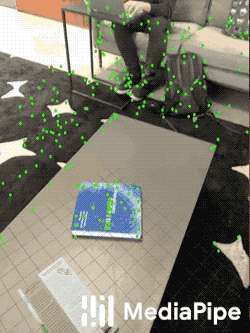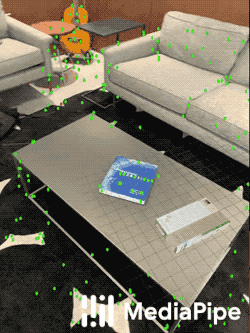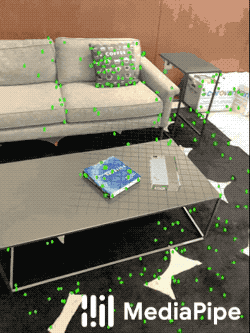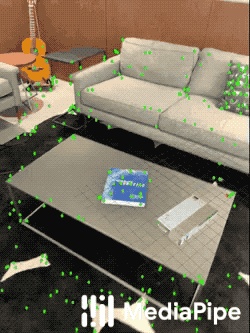
*Fig 4. An example of AR synthetic data generation. The virtual white-brown cereal box is rendered into the real scene, next to the real blue book.* |
|
||||
|
||||
@@ -107,7 +107,7 @@ takes the image crop and estimates the 3D bounding box. At the same time, it
|
||||
also computes the 2D crop of the object for the next frame, such that the object
|
||||
detector does not need to run every frame.
|
||||
|
||||
 |
|
||||
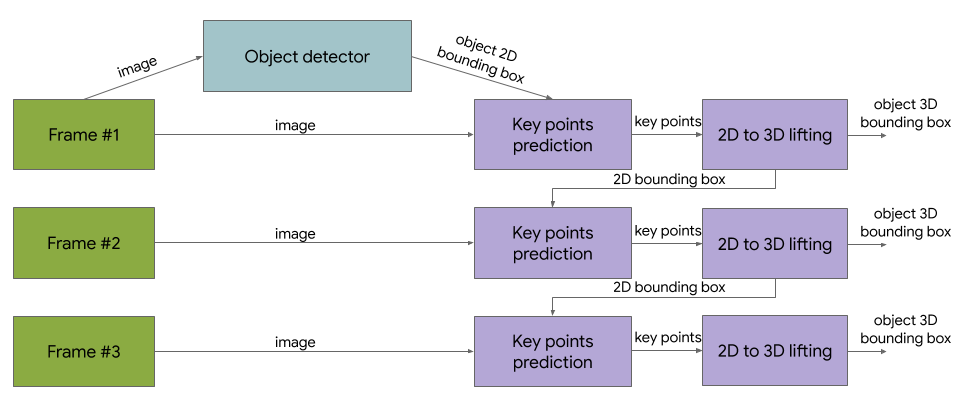 |
|
||||
:----------------------------------------------------------------------------------------: |
|
||||
*Fig 5. Network architecture and post-processing for two-stage 3D object detection.* |
|
||||
|
||||
@@ -119,7 +119,7 @@ mobile GPU.
|
||||
|
||||
### Single-stage Pipeline
|
||||
|
||||
 |
|
||||
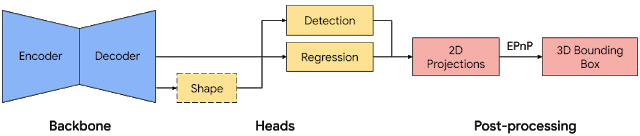 |
|
||||
:---------------------------------------------------------------------------------: |
|
||||
*Fig 6. Network architecture and post-processing for single-stage 3D object detection.* |
|
||||
|
||||
@@ -144,7 +144,7 @@ object dimensions. Given the 3D bounding box, we can easily compute pose and
|
||||
size of the object. The model is light enough to run real-time on mobile devices
|
||||
(at 26 FPS on an Adreno 650 mobile GPU).
|
||||
|
||||
 |
|
||||
 |
|
||||
:-------------------------------------------------------------------------------------: |
|
||||
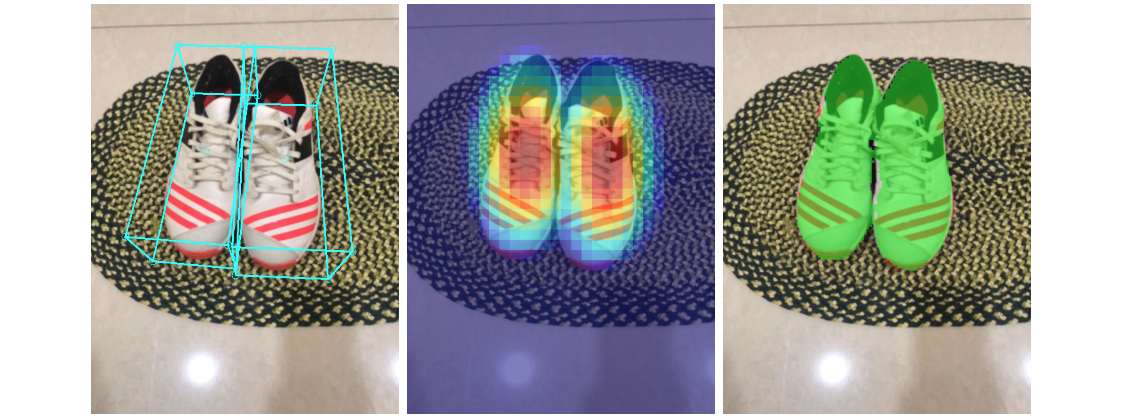
*Fig 7. Sample results of our network — (Left) original 2D image with estimated bounding boxes, (Middle) object detection by Gaussian distribution, (Right) predicted segmentation mask.* |
|
||||
|
||||
@@ -573,7 +573,7 @@ Each object has its object coordinate frame. We use the below object coordinate
|
||||
definition, with `+x` pointing right, `+y` pointing up and `+z` pointing front,
|
||||
origin is at the center of the 3D bounding box.
|
||||
|
||||

|
||||

|
||||
|
||||
### Camera Coordinate
|
||||
|
||||
@@ -582,7 +582,7 @@ regard to the camera coordinate frame. In this API we use the below camera
|
||||
coordinate definition, with `+x` pointing right, `+y` pointing up and `-z`
|
||||
pointing to the scene.
|
||||
|
||||

|
||||

|
||||
|
||||
To work with box landmarks, one can first derive landmark coordinates in object
|
||||
frame by scaling a origin centered unit box with `scale`, then transform to
|
||||
@@ -599,7 +599,7 @@ In this API we use
|
||||
as an intermediate space when projecting points from 3D to 2D. In NDC space,
|
||||
`x`, `y` are confined to `[-1, 1]`.
|
||||
|
||||

|
||||

|
||||
|
||||
By default the camera parameters `(fx, fy)` and `(px, py)` are defined in NDC
|
||||
space. Given `(X, Y, Z)` of 3D points in camera coordinate, one can project 3D
|
||||
|
||||
Reference in New Issue
Block a user